Type a question into a search box and, in less than a second, you get a tidy list of answers drawn from billions of pages. It feels like magic, but it is really a huge, well-organised system working in three stages. Understanding how search engines work helps you make sense of why some pages rank first, why brand-new pages take time to appear, and why search results change from person to person. This guide walks through crawling, indexing, and ranking in plain language, explains how a search engine answers your query the moment you press enter, and clears up the most common myths along the way.
Stage One: Crawling — Finding the Pages
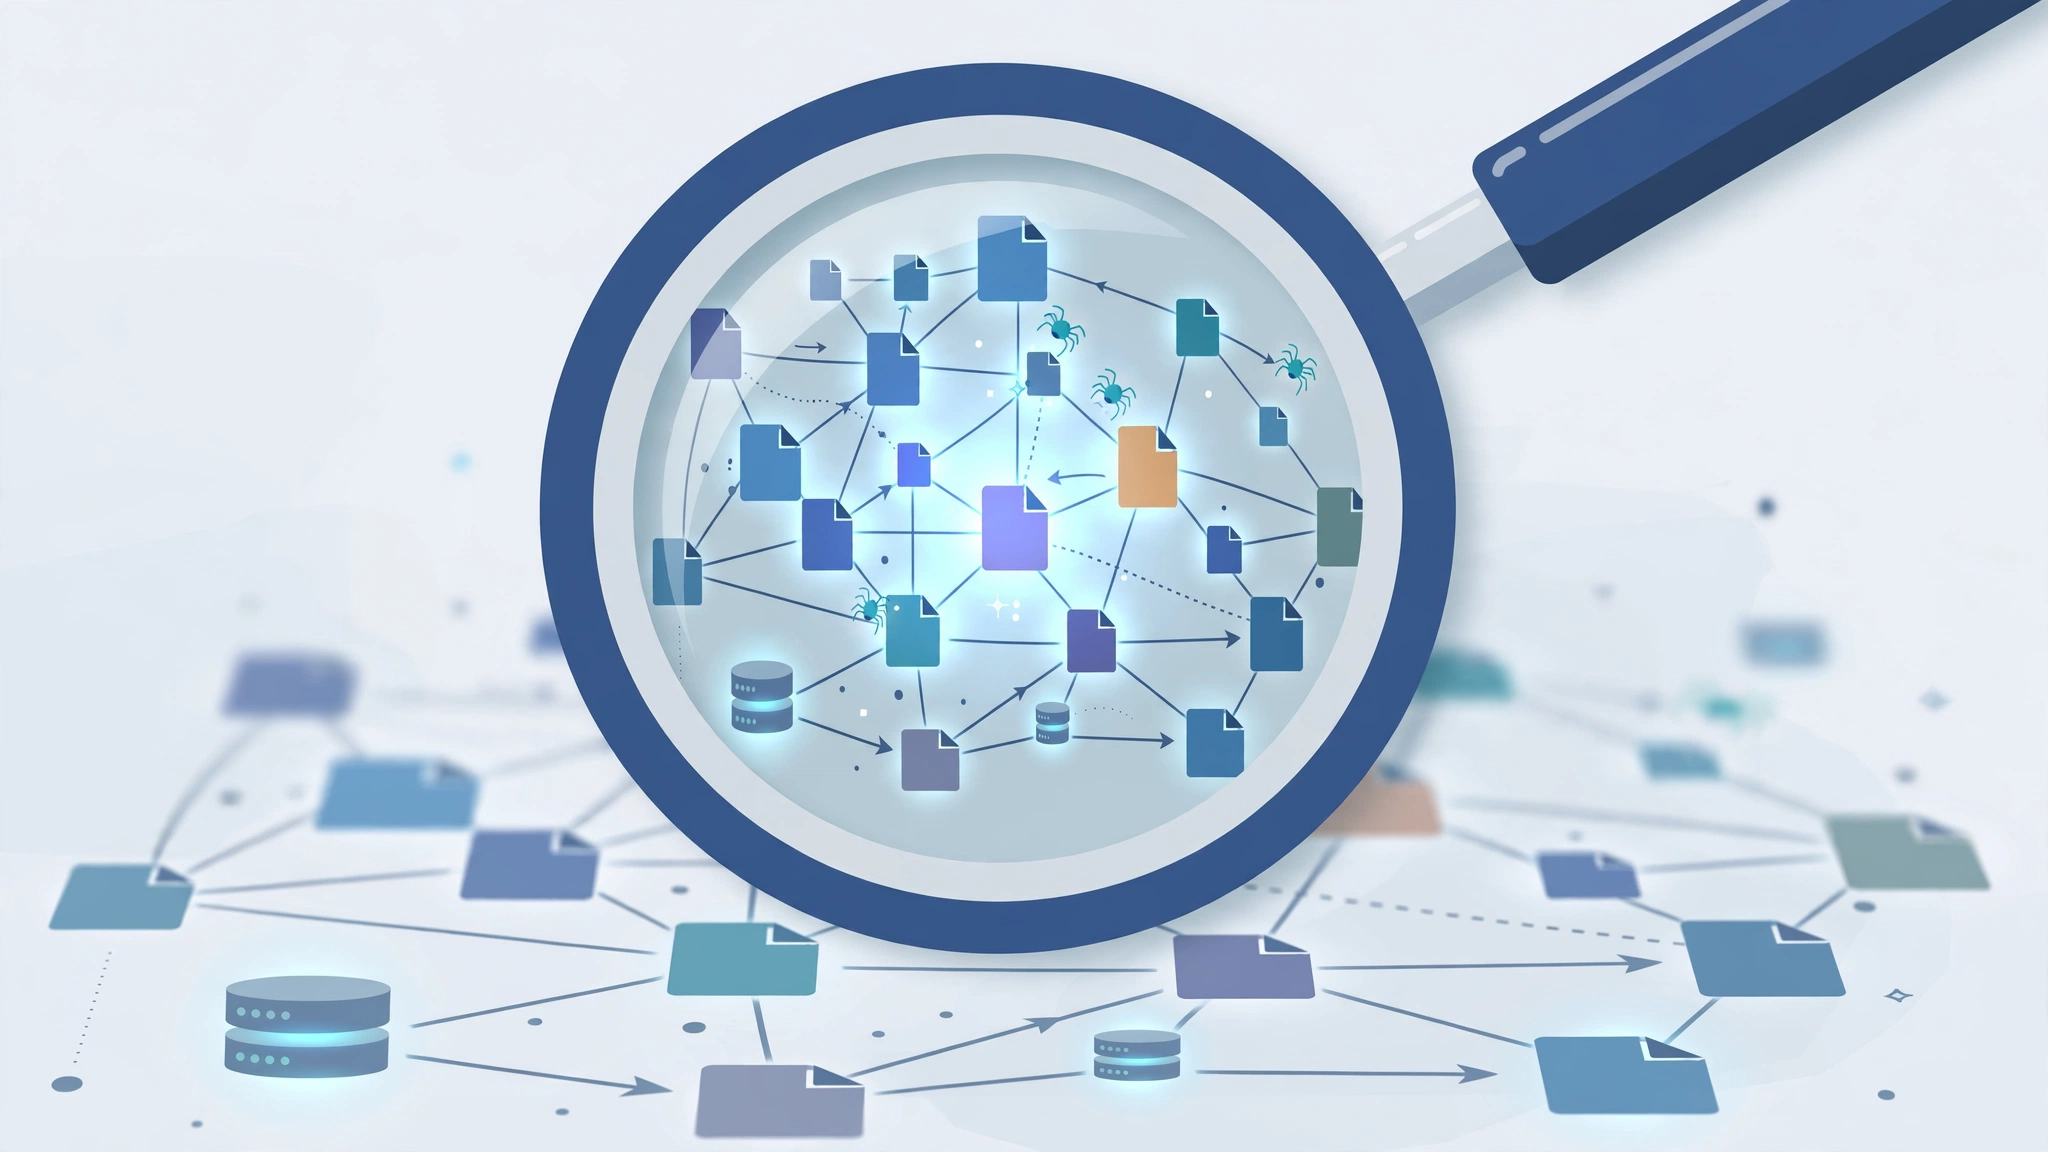
Before a search engine can show a page, it first has to find it. Search engines use automated programs called crawlers, bots, or spiders. Google’s is called Googlebot. A crawler starts from a list of known web addresses and follows links from page to page, constantly discovering new pages and revisiting old ones to check for changes.
How Crawlers Move Around the Web
Links are the roads of the internet. When a crawler visits a page, it reads the links on that page and adds them to its queue of places to visit next. Site owners can speed up discovery by submitting a sitemap, a file that lists the important pages on a site, through tools such as Google Search Console. Crawlers do not visit every page equally. Popular, frequently updated sites may be crawled many times a day, while a small, rarely changed page might be visited every few weeks. This budget of attention is sometimes called crawl budget, and it is one reason large sites work hard to keep their internal linking clean and their servers fast.
What Crawlers Respect and Skip
Site owners guide crawlers with a file called robots.txt, which can tell bots which sections of a site to leave alone, such as admin pages or duplicate print versions. A page can also carry a noindex instruction that allows crawling but asks the engine not to show the page in results. Crawlers cannot log in, fill in most forms, or see content hidden behind paywalls unless the owner provides access, which is why some perfectly good pages never appear in search at all. When a crawler visits, it downloads the page much like a browser does, including text, images, and code, and passes everything it finds to the next stage.
Stage Two: Indexing — Building the Library
Finding a page is only half the job. The search engine then has to understand it and store it in a way that allows instant retrieval. This store is called the index, and it is best imagined as a gigantic library catalogue. Instead of shelving books, the index records every significant word on every page and where it appears.
How a Page Is Processed
During indexing, the engine renders the page, which means it loads it like a real browser, running the code so it can see content that appears with JavaScript. It extracts the text, titles, headings, images, and videos, and analyses what the page is about: its topic, its language, its location relevance, and how fresh it is. It also groups near-duplicate pages together and picks one canonical version to show, so the same article reachable from three different addresses does not appear three times in results. Pages that are thin, duplicated, or blocked by a noindex tag may be crawled but left out of the index entirely.
Why Indexing Takes Time
A new page is not searchable the instant it is published. The crawler has to discover it, visit it, process it, and add it to the index, and each step can take hours, days, or occasionally weeks. Site owners can request indexing for important new pages, but the engine still decides when to crawl and whether the page earns a place. This delay surprises many beginners, who publish an article and search for it five minutes later. The system is simply enormous: the index contains hundreds of billions of pages and is constantly being rebuilt as pages appear, change, and disappear.
Stage Three: Ranking — Choosing the Order
The index may hold millions of pages that match your words. Ranking is the process of deciding which handful deserve the top spots. When you search, the engine scores candidate pages using hundreds of signals, then orders them in a fraction of a second.
The Signals That Matter Most
Relevance comes first: does the page actually cover what you asked, in the depth you probably want? The engine looks at words in the title, headings, and body, but modern systems go far beyond exact matches. They understand synonyms, entities, and intent, so a search for “fix a dripping tap” can surface a plumbing guide that never uses that exact phrase. Quality and trust matter next. Pages that demonstrate real expertise, cite sources, and are recommended by other reputable sites through links tend to rank higher. Links act like votes of confidence, an idea from Google’s original PageRank system that still influences ranking today, though a few strong, relevant links now outweigh hundreds of weak ones.
Usability, Freshness, and Context
A page that loads slowly, jumps around on screen, or is unreadable on a phone will struggle, because search engines measure real user experience signals such as loading speed and mobile friendliness. Freshness matters when the topic demands it: results for “election results” or “weather tomorrow” favour the newest pages, while “how to tie shoelaces” does not. Context personalises the rest. Your location, language, device, and recent search history all shape the list, which is why two people in different cities rarely see identical results. Increasingly, search engines also use systems built on AI automation and machine learning to interpret ambiguous queries, detect spam, and understand the meaning behind words rather than just matching them.
What Happens in the Second You Search
With the library built, answering a query is a retrieval race. The engine interprets your words, correcting spelling, expanding synonyms, and guessing intent: are you looking to buy something, learn something, visit a specific site, or go somewhere nearby? It then pulls the strongest candidate pages from the index, scores them with its ranking systems, removes duplicates, and assembles the results page. That page is more than ten blue links. Depending on the query, you may see a map pack for local businesses, images, videos, shopping listings, a featured snippet that quotes a page directly, or an AI-generated overview that summarises several sources. Each element is chosen because the engine predicts it is the fastest route to a satisfying answer.
Advertisers appear through a separate auction that runs alongside the organic results. Ads are labelled, and paying never improves a page’s unpaid ranking, a separation search engines guard carefully because trust in the organic results is their whole product.
Not Just Google: The Wider Search World
Google handles the large majority of searches in most countries, but it is not the only engine. Microsoft’s Bing powers results for several other services and has invested heavily in AI-assisted answers. DuckDuckGo attracts users who want results without personalised tracking. Baidu dominates in China and Yandex in Russia, each tuned to local language and rules. Meanwhile, a growing share of “search” now happens inside other apps: people look for products on Amazon, videos on YouTube and TikTok, and local recommendations in map apps. Each of these is a search engine in its own right, with its own crawling, indexing, and ranking logic, even if the library it searches is limited to one platform.
Common Myths About Search Engines
Myth one: you can pay to rank first organically. You cannot. Paid placements are ads, clearly separated from unpaid results. Myth two: repeating a keyword many times boosts ranking. That tactic, called keyword stuffing, now harms pages; engines understand topics, not just word counts. Myth three: new sites cannot rank. New sites start without trust, but a focused page that genuinely answers a specific question can outrank older, weaker pages surprisingly quickly. Myth four: there is one secret trick. Ranking is the sum of relevance, quality, links, usability, and context. The durable strategy is unglamorous: publish genuinely helpful pages, earn real recommendations, keep the site fast and easy to crawl, and be patient while the index learns to trust you.
What This Means If You Run a Website
Once you understand the three stages, most good search engine optimisation stops being mysterious and starts being common sense. For crawling, make your site easy to explore: link your important pages from menus and from related articles, keep a clean sitemap, and fix broken links that waste the crawler’s time. For indexing, give every page one clear topic, a descriptive title, and content substantial enough to deserve a place in the library; thin pages that add nothing are often crawled and quietly dropped. For ranking, the work is slower but simpler: publish the most helpful answer you can, earn links by being worth citing, keep pages fast and readable on phones, and update important articles as facts change.
A Simple Routine That Works
Check Search Console every few weeks to see which queries already bring you impressions, which pages Google has indexed, and whether any crawl errors need attention. Improve pages that rank just below the top spots before writing new ones, because they have already proven their relevance. Add internal links from your strongest pages to the ones you want to lift. None of this is a trick, and none of it works overnight, but it compounds: each helpful page strengthens the trust of the whole site, and trusted sites get crawled more often, indexed more completely, and ranked more generously. That feedback loop, not any secret setting, is how small sites grow into big ones.
Frequently Asked Questions
How long does it take for a new page to appear on Google?
Anywhere from a few hours to several weeks. The crawler must discover the page, visit it, and add it to the index. Pages on established, frequently crawled sites usually appear fastest. Submitting a sitemap and requesting indexing in Google Search Console can help discovery, but neither guarantees instant inclusion.
Why do my search results differ from someone else’s?
Because ranking uses context. Location, language, device, and search history all influence which pages are judged most relevant for you. Someone searching in another city, or logged out on a different device, will often see a noticeably different order for the same words.
Can a website stop a search engine from listing it?
Yes. A robots.txt file can block crawlers from visiting parts of a site, and a noindex tag tells the engine to leave a page out of results even if it was crawled. Site owners use these tools for admin areas, thank-you pages, and other content that should exist for visitors but not appear in search.
The Bottom Line
Search engines work by crawling the web to find pages, indexing them into a vast searchable library, and ranking them in a split second using relevance, quality, and context. Once you see the system as a library rather than a mystery, the rules of visibility become clear: make pages worth finding, make them easy to crawl and understand, and earn the trust that moves you up the list. Whether you are searching or publishing, that simple three-stage picture explains almost everything you will ever observe about why results look the way they do.